edh-tool
Popularity-ranked deck tools steer every Commander player toward the same cards. edh-tool uses AI-tagged card data to find the strong ones nobody is playing.
- 12,580cards tagged by AI
- 792commanders with themes
- $12.41for the full tagging run
- Problem
- Sites like EDHREC rank cards by how often they're already played, so a strong card nobody has heard of looks exactly like a weak one. Players end up building the same decks.
- What I built
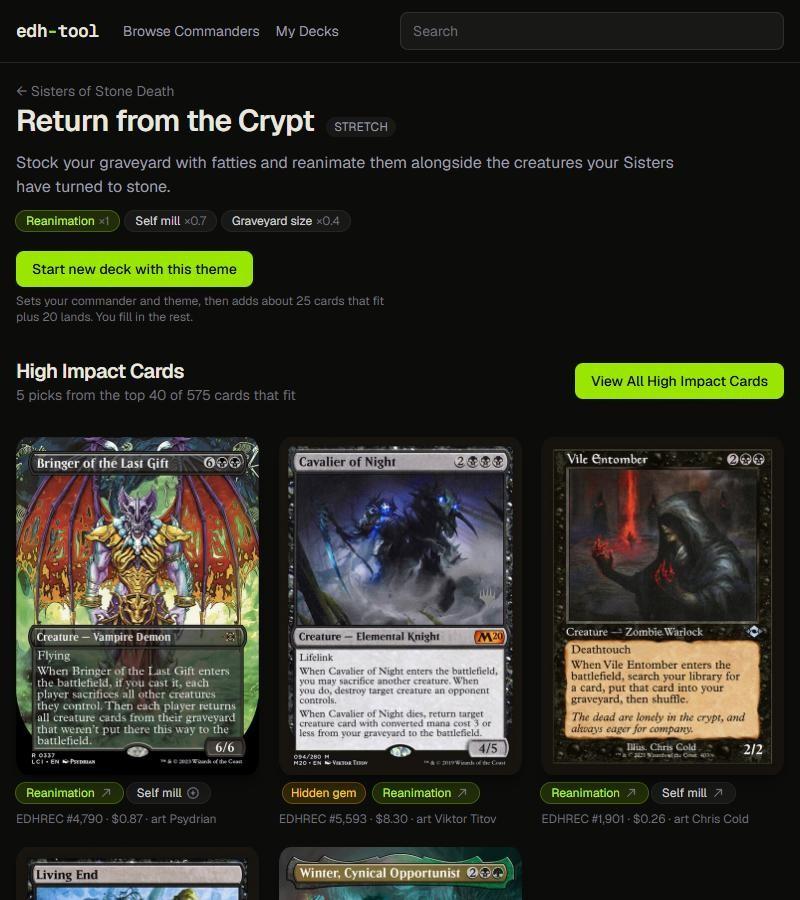
- An offline Python pipeline that has Claude tag each card against an 80-tag vocabulary and write themes for each commander, a dependency-free JavaScript scoring engine, and a Next.js site with theme recommendations, a browser-based deck builder, and Moxfield/Archidekt export.
- My role
- Solo developer, with Claude Code as a pair-programmer: product design, the AI pipeline, the scoring model, and the full-stack site, from Postgres schema to UI. I compared models against a hand-tagged set before committing to the full run.
- Outcome
- 12,580 cards tagged and 4,463 themes generated across 792 commanders, live at edh-tool.com. Trimming the model's output format cut output tokens by 68% while still matching hand tags just as closely, bringing the full tagging run to $12.41.
How it works
One scoring engine everywhere
Each card's score is fit × commander synergy × quality × popularity × art match, computed by a single pure-JS module that runs in the API routes, the CLI, the tuning bench, and the tests, so a score on the site is the same score everywhere. Five picks per theme are drawn by seeded weighted sampling, so a player's list stays stable while they build, and two players with the same commander still see different cards.
Separating unknown from bad
The obscurity bonus uses log rank, because popularity follows a power law, and it's gated by the model's quality estimate so obscure junk never gets lifted. Across 200 simulated players, each theme surfaces 21–40 distinct cards.
Choosing the model with data
Sonnet and Haiku tagged the same 221 cards and were scored against hand tags. Haiku found tags about as often but rated weak cards 0.59 versus Sonnet's 0.34, which would have broken the gem filter. I picked Sonnet and cut cost with the Batch API and a slimmer output format instead of a smaller model.




 linkedin.com/in/jackson-schacher
 jschacher8@gmail.com